You Can't Sticker Your Way to a Database
Slapping Data Governance, Stewardship, and a "Data Catalog" (really a Data Dictionary) onto data structures no strong data person ever designed, because: "files", is the same as slapping metadata on files and expecting the benefits of a database just because you write SQL on top of it.
Every few years we try to rebuild the "database". First it was MapReduce, now it is metadata on files.
I remember a few years ago, I was working at a startup. The database went down, and the CEO bellowed "Can't we just turn this into files, so it never goes down?"
In the end, the "files" guys won, which they are pretty happy about, because Data Modelers/Architects always slowed them down, in their opinion.
Witness the decline of the data people, now the “files” guys want the Data Governance people to fix it.
Because, in the end, AI does not understand what was built.
Slapping Data Governance, Stewardship, and a "Data Catalog" (really a Data Dictionary) onto data structures no strong data person ever designed, because: "files", is the same as slapping metadata on files and expecting the benefits of a database just because you write SQL on top of it.
Tell me why I'm wrong.
We had to do some of what has happened because of the profusion of data sources, especially unstructured data, and effective use of Data Producers and Consumers and parallelism.
What did we lose, and what are we continually working around?
We got away with "metadata on files" for one reason: experienced data people silently supplied the meaning the structure didn't. That was the hidden subsidy. Hand that same pile of files to an agent, and the subsidy is gone. The agent reads a valid catalog and still gets the meaning wrong, because a Data Catalog that's really a Data Dictionary tells it what a field is called, not what it's for. And a guessing agent doesn't fail loudly. It fails plausibly: confident, well-formatted, and wrong three systems downstream.
The answer isn't to un-build the lake or fire the "files" guys. They solved a real problem with unstructured data and scale. The answer is to put the modeling discipline back above the physical layer: a governed semantic model of what the entities mean, independent of whether they live in files, tables, or a catalog.
That's the layer an agent can actually trust.
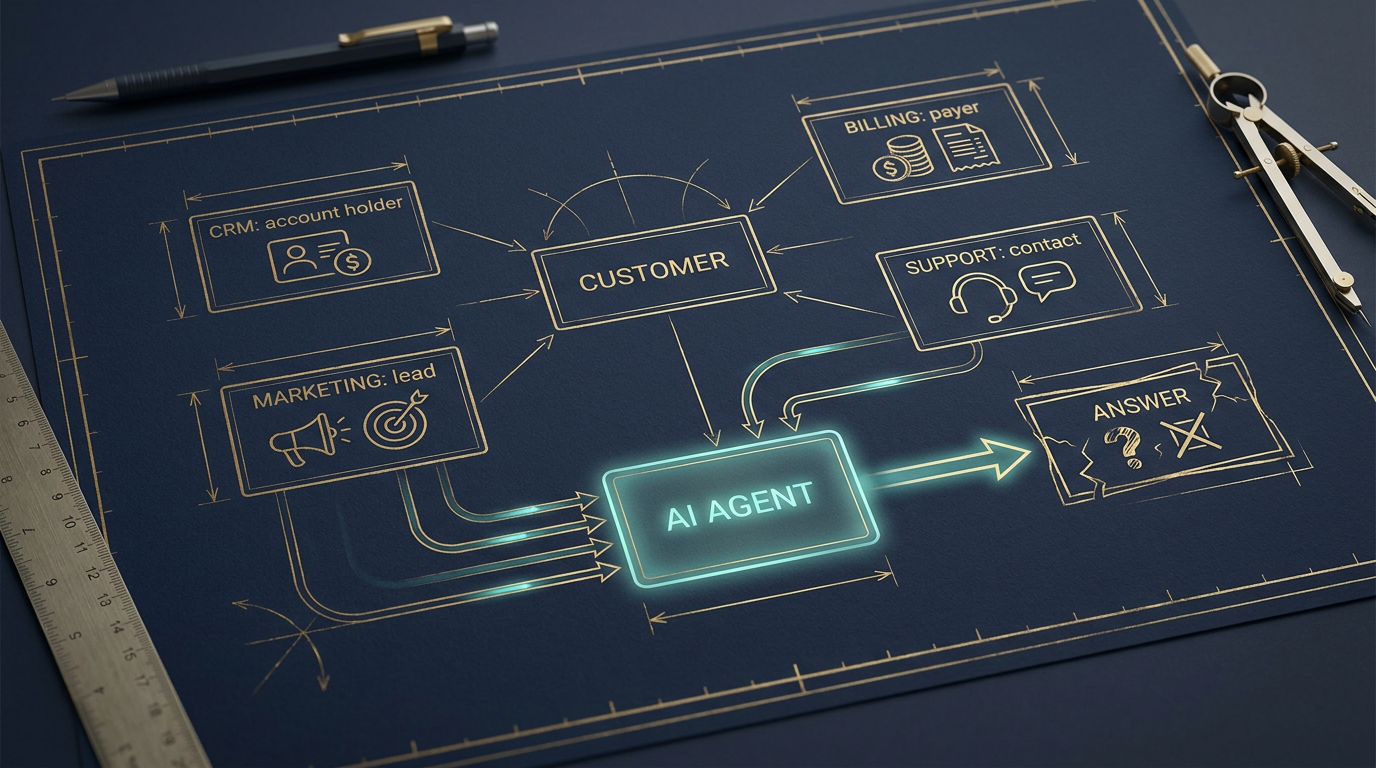
Plausibly Correct, Evidently Wrong: Why Enterprise Meaning Needs a Living Ontology
Plausibly Correct, Evidently Wrong: Why AI Needs a Living Ontology, Not a Data Catalog
Enterprise meaning has to become a living framework - auditable, and updated because it must be, because it’s a runtime component of machine and analyst use and decision-making, if it’s going to be governed and actionable by machines or people.
So today I’m reading different thought leaders and reconciling their proposed solutions against what I know about entropy, organizations, data, and every prior attempt to solve this.
I agree with this: "While data catalogs focus on documenting datasets, schemas, lineage, and ownership, pragmatic ontology defines domain objects and relationships that are directly usable by both humans and AI agents at runtime." — Emmanuel Klinger
Throwing gold-layer metadata into a repository, graph, or vector won't cut it.
The models are already showing us the gap.
They guess for you: plausibly correct, evidently wrong, and it’s what your analysts have been telling you for years, it's what is discovered after using dashboards for a few months.
You just weren’t listening until a machine said it: by producing reasonably deduced but wrong outputs.
Outputs you are now authorizing it to act on, unsupervised.