When "Always Populated" Isn't
Cheryl Dopp | AINOW | Data Key Design Mistakes Break AI Projects
A Multi-Million Dollar Lesson in Data Assumptions
A company set out to build a new loan identifier for a residential mortgage data feed. An industry-standard identifier already existed, but the business wanted its own, so the initiative moved forward at the executive level, and every related team scrambled to deliver it.
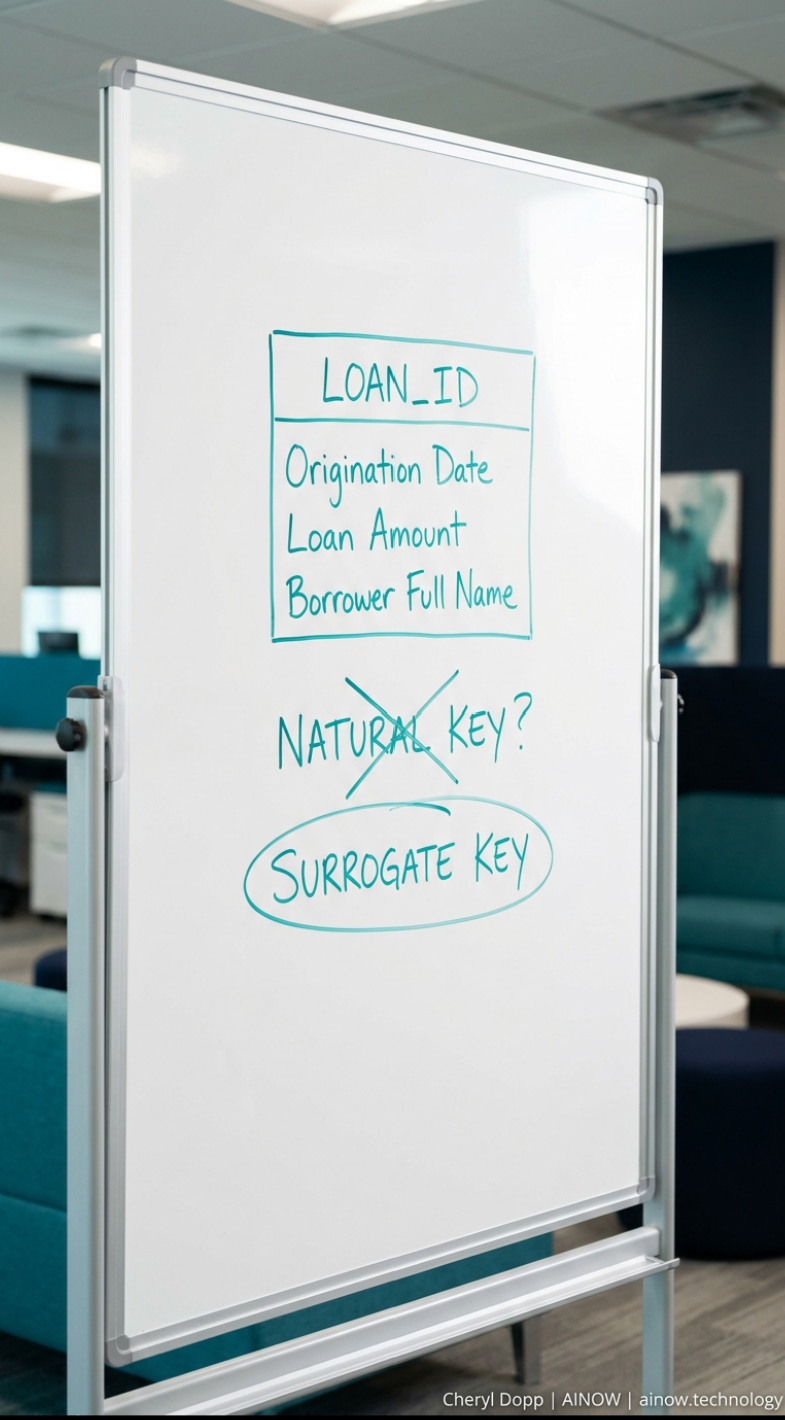
The design team needed a key that would always be present, always be valid, and always produce a unique row for every loan. The candidate they settled on included the loan's origination date, a field everyone assumed would always be populated, since how else would you calculate an amortization schedule or a payoff amount?
That assumption was never checked against the data the company already had.
One member of the team objected. He argued for a surrogate key: an internally generated identifier that could be remapped without breaking every downstream consumer of the feed if the underlying business fields ever proved unreliable. He was overruled, and the business proceeded with the natural key.
The feed broke within months of launch and was abandoned within a year.
Why "should always be true" and "is always true" are different questions
Every data system runs on rules like these: this field is required, this combination is unique, this value never changes once set. Those rules describe intent. They are not a guarantee about what the data actually contains.
Real systems produce exceptions to nearly every rule eventually. Two people enter the same record minutes apart, unaware of each other. A closing gets scheduled but the system is never updated after it happens. A row gets rejected for one reason, corrected, and reintroduced with a gap in its history. None of these show up in a requirements document. All of them show up in production.
A rule that fails once in ten thousand records is enough to break a feed that assumes it never fails.
The same risk now applies to AI
AI systems built on top of your data inherit the same assumptions your business rules encode. If a semantic layer describes a field as always populated and always unique, a model built on that layer will treat the description as fact, right up until the data contradicts it. Faster deployment just means the failure surfaces sooner and touches more processes.
What we check before a client builds on an assumption
Before we help a client design an identifier, a matching strategy, or an AI pipeline around a field, we test the assumption against the data itself rather than the documentation describing it:
Is the field actually populated in every record, or only in most of them?
Does the proposed combination of fields produce a genuinely unique row, or does it collide under real volume?
Can any component of the key be corrected or reissued after the fact, and what happens to the identifier if it is?
What is the fallback when the assumption fails, and how much does it cost to remap without breaking every consumer downstream?
We also recommend a design that does not require the business key to be perfect: a stable, internally generated surrogate key, paired with the natural key for matching, traceability, and communication with data consumers.
Natural keys work fine when their assumptions hold. The lesson is that nobody tested whether they held, and the cost of skipping that test landed on the business, not the data model.
If your team is designing a new identifier, building a matching strategy, or preparing data for an AI system that assumes clean, complete, unique inputs, we help you find out what is actually true in your data before you build on it, and we design the fallback for when it isn't.